Our first scheduling agent was built the way most agent tutorials say to build one. The model sat in a loop with a list of tools. It read the request, picked a tool, read the result, picked the next tool, and decided when it was done. We took the model out of that loop. This post covers what we saw, what we built instead, and what it cost us.
Some context. We build ANCI, an agent that schedules meetings for executive assistants over chat and email. A request like "move my 2pm with Sam to Thursday" sounds trivial, but it is five or six decisions: which meeting, which Sam, which Thursday, whose calendars, and who gets told. A wrong answer is not a bad paragraph. It is an invitation sitting in someone else's inbox.
What the model controlled
Our first agent, Zara, ran Claude in a tool-use loop, with a cap on turns and a budget cap of $1 per request. A meeting request exposed more than 20 tools: classify the intent, look up an attendee, find availability, ask the host a question, build a plan, review the plan, book. The model chose the order, and the model decided when the request was finished.
It demoed well. Short, clean requests went through in a few turns.
What a hallucination cascade looks like
It rarely looked like the model inventing a fact. It looked like a reasonable early guess that every later step trusted. Three examples from our own bug tracker:
- A skipped step. Someone asked to meet "the Product team and financ". The model was supposed to look the names up first. Sometimes it skipped the lookup and asked the host "did you mean the Finance team?", a question it could have answered itself. We made the lookup a hard rule in the prompt. It still skipped it now and then, so we added code that refused the question until the lookup had run.
- A silent finish. Asked "who is in financ", the model got a vague result back and ended its turn. No reply ever went out. The fix was a fallback in code that noticed the loop had ended without a reply, and sent one.
- A number that meant two things. We emailed the host a numbered list of times, sorted by how close each was to the requested time. The list the model used to read the reply was in date order. A reply of "Option 1" went to the model to interpret over two lists that disagreed, and it could book a time the host had never seen.
None of these is exotic, and each one was fixed. But look at the shape of the fixes: a forced review step that hid every tool but one; a gate that hid the booking tool until the required fields were filled; a handler that refused a question; a fallback for a reply that never came. Every fix was code taking a decision back from the model. And the forced steps each added a model call or two, so latency and cost went up with every fix.
The other lesson was about measurement. On requests we had already tested, the agent looked about 95% right. On phrasings it had never seen, it did much worse. And small errors multiply across chained decisions: 95% per step over five steps is about 77% for the whole request.
The new pipeline
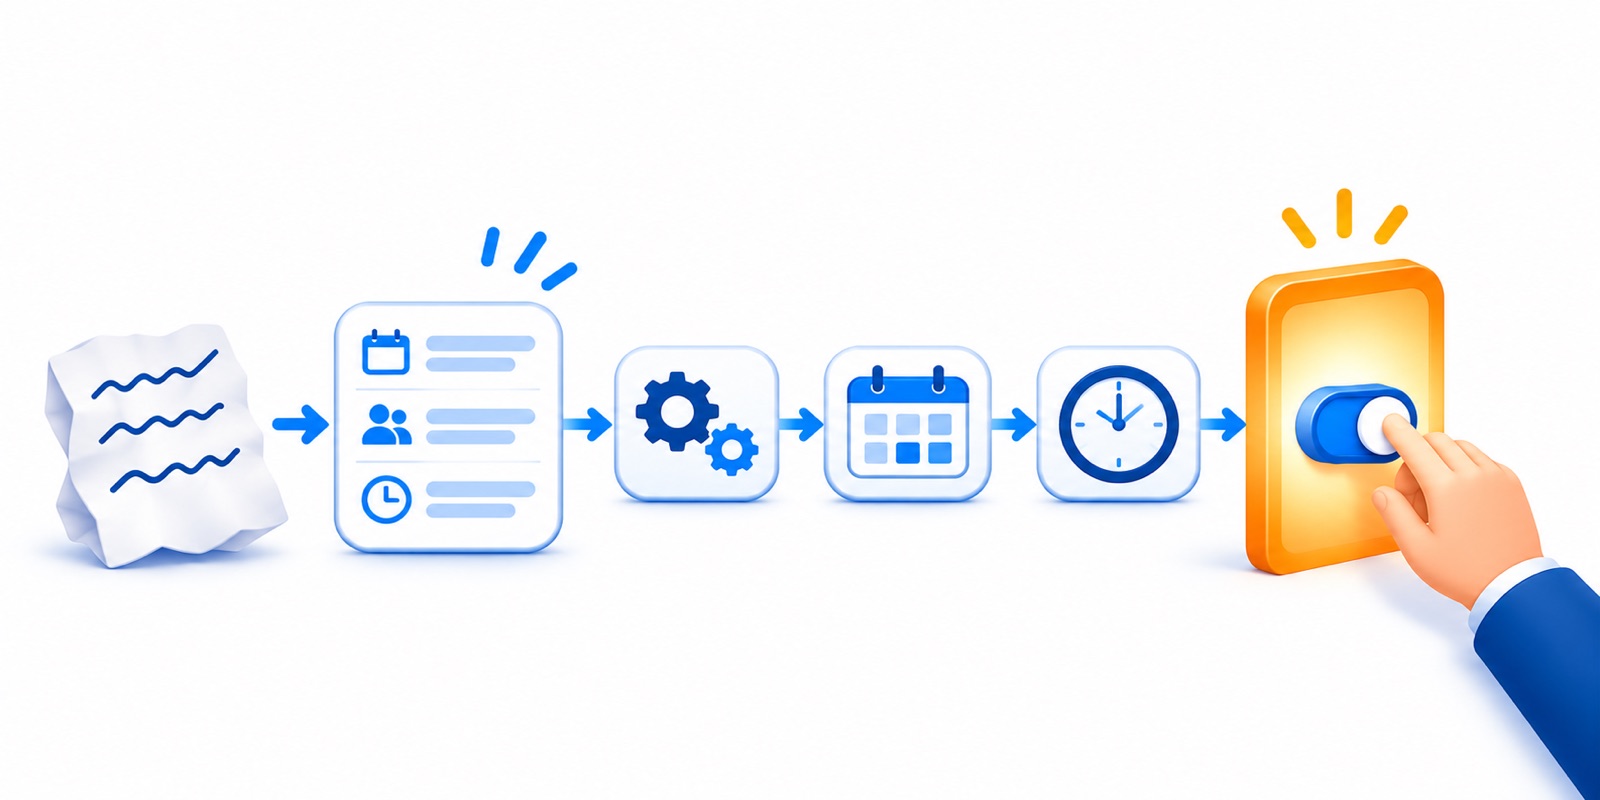
The rebuild started from one question: which part of this problem actually needs a language model? The answer was reading, turning "can u set something up w Dan from Acme next week" into a structured request. Everything after that is a function of the request and the calendar, so it should be ordinary code.
The model's job got small enough to test like a parser: given this message, the form should be this. We keep suites of situations, each with one correct outcome and many phrasings, and we score on a held-back half we never tune against. Each phrasing runs three times, because the model still isn't deterministic, and passes only if all three runs are right. A short list of serious errors blocks a release whatever the overall score:
wrong person invited
mail the host didn't approve
a "free" time not read from a real calendar
What we gave up
This isn't free, and the trade-offs are real.
- Range. The old agent would attempt anything. The new one handles the request types we have built, and outside them it says so or asks. We had to list the use cases up front instead of hoping the model would generalize.
- Questions. When a read is uncertain, the agent asks instead of guessing. Some of those questions are ones a good human assistant wouldn't need to ask. We track that rate and hold it under a ceiling of 15%, but it isn't zero.
- Speed of adding features. A new capability used to be a new tool and a paragraph of prompt. Now it is a form field, code, and a suite of phrasings before it ships.
- Cleverness. Once in a while the old loop found a creative path through an odd request. That's gone. For scheduling it is the right trade: a wrong booking costs a relationship, and an extra question costs a few seconds.
It isn't perfect either. The reading step still misreads; on requests it has never seen, it still gets about 1 in 16 wrong. The difference is where those misses land: as a question or a card the assistant corrects, not as an invitation in somebody's inbox.
When I'd still let a model run the loop
If mistakes are cheap and reversible, as in research, drafting, or code you will review, a model-driven loop is great and the flexibility is worth it. The test I use now is to find the first step that can't be undone. Everything before it can be as agentic as you like. Everything at and after it should be code you can read and test, with a person standing at the line.
Further reading: Varsha Sivaprakash's AI Agents Should Be Mostly Deterministic. Here's Why, and my post on why 95% isn't good enough for an executive's calendar. We build ANCI for executive assistants. If you're building agents and want to compare notes, find me on LinkedIn.